Audio-to-Text Transcription
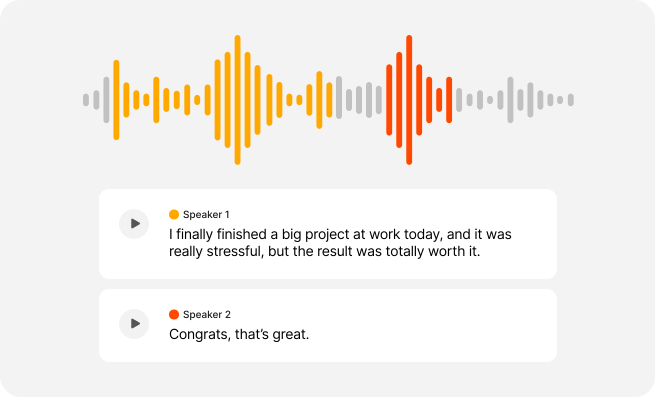
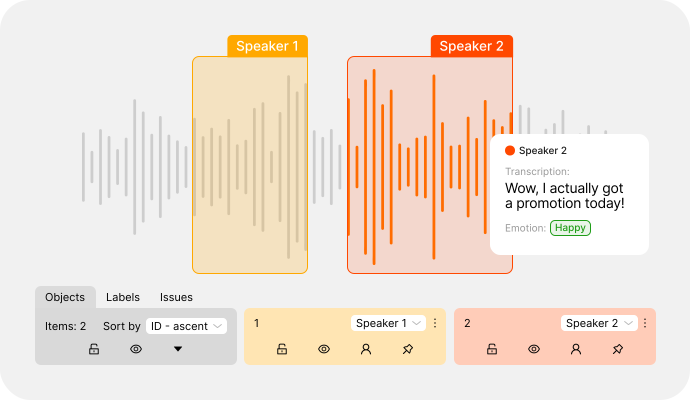
We transcribe speech recordings into structured text labels.
- Multi-language transcription
- Multi-speaker transcription with speaker-separated tracks
- Transcriptions for separate letters, words or whole phrases
Beyond Vision: CVAT Goes Multimodal and Introduces Audio Annotation. Learn more

Hand off high-volume audio transcription and speech labeling to trained teams. We run the workflow, quality control, and delivery so you get datasets ready for voice AI.
Trusted by leading AI teams
We support a wide range of speech and audio labeling tasks across single-speaker, multi-speaker, and non-speech recordings, delivering reliable annotations tailored to your AI model’s needs.
We transcribe speech recordings into structured text labels.
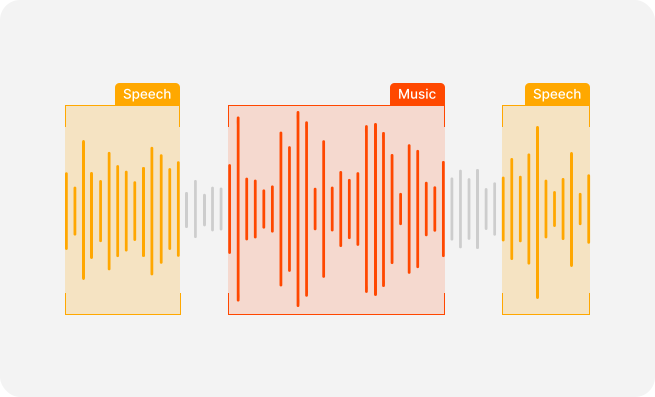
We split recordings into timestamped regions of interest so labels map to exact time intervals.
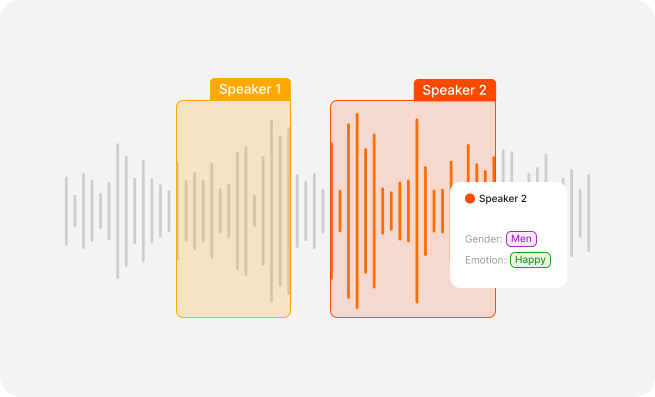
We assign categorical labels to speaker tracks or segments based on your labeling schema.
From speech recognition datasets and call analytics to voice-enabled devices and accessibility workflows, we help teams turn raw audio into high-quality labeled data for real-world AI solutions.
Speech transcription for ASR training, plus speaker separation and optional attributes.
Transcription and segmentation for long calls, with speaker-level labeling and metadata.
Captions, transcripts, and speaker separation datasets for meeting search and accessibility features.
Voice-enabled product datasets that need transcription, segmentation, and consistent labels.
In-cabin speech data labeling for noisy environments and multi-speaker scenarios.
Subtitles and searchable audio archives with time-aligned transcripts.
Speech datasets for dictation and clinical audio, with security-first handling where required.
Audio event segmentation and classification for underwater monitoring.
Contact us to discuss your project.
Step 1
Submit a small sample of your audio data for a free proof of concept. We label it using an agreed scope and guidelines, so you can review quality, turnaround time, and deliverables before committing.
Step 2
We prepare a detailed proposal based on the confirmed scope. It includes pricing, delivery schedule, batch structure, and the exact output formats you will receive.
Step 3
Our annotation team labels your full dataset at scale, following the approved guidelines. You get regular updates and staged deliveries based on the agreed cadence.
Step 4
We run manual and automated quality checks to verify consistency and accuracy against the agreed criteria. You receive clear QA reporting with each delivery stage.
Step 5
We deliver the complete labeled dataset in the agreed format, along with a QA summary and final project notes for handoff to your ML team.
We take data protection seriously, from legal safeguards to technical controls.
All projects are governed by strict NDAs, and we follow GDPR and CCPA principles for data handling.
CVAT supports integration with your own cloud storage (AWS S3, Azure Blob, or Google Cloud), so your data never has to leave your environment.
Each labeling project has its own isolated workspace with role-based access available to you and your annotation team.
From one-time to long-term annotation projects with evolving datasets, we adapt to your workflow, not the other way around.
| Plan | Complete Dataset | Incomplete Dataset |
|---|---|---|
| Payment terms | Pay after labeling is complete | Pay upfront, use over time |
| Minimum budget | $5,000 | $5,000 |
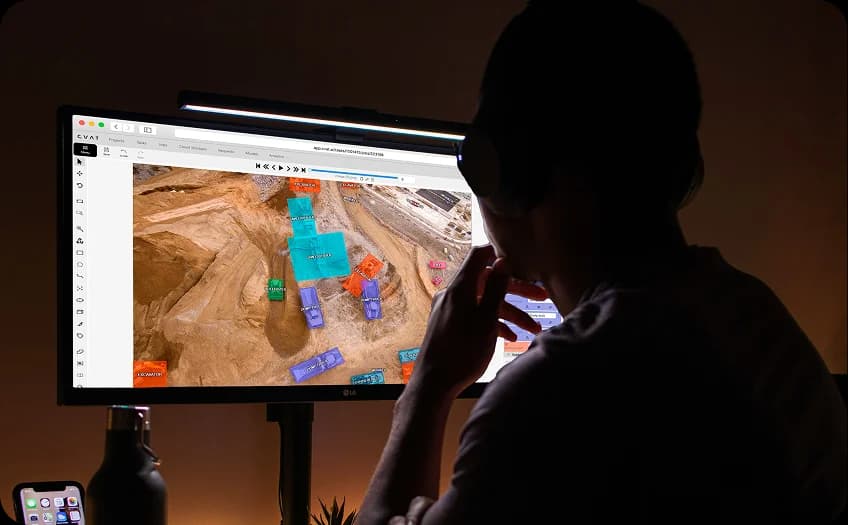
We work with a broad range of speech and audio data, including single-speaker and multi-speaker recordings, long-form calls and meetings, voice assistant and IoT audio, in-cabin automotive recordings, clinical dictation, captioning workflows, and others.
Our workflows cover transcription, timestamped segmentation, speaker-separated tracks, and classification or attribute tagging.
On the format side, we are set up for common audio inputs such as MP3 and WAV, with cloud-based ingestion and audio processing workflows designed for scalable annotation.
We combine upfront scope alignment, approved annotation guidelines, pilot calibration, staged production reviews, and both manual and automated QA.
Depending on the task, our quality controls can include ground-truth validation, IoU checks for timestamped segment matching, and WER/CER-based evaluation for transcription quality.
We also provide clear QA reporting with each delivery stage so quality is visible and measurable throughout the project.
Yes. We support multilingual transcription and can adapt workflows for dialect- and accent-specific audio.
For each project, we define annotation schemas tailored to your data and requirements, including different languages, pronunciation patterns, accents, and other speech variations.
This can include multiple transcription attributes within the same segment when needed, allowing us to handle dialect-specific use cases more accurately instead of forcing everything into a single generic transcription workflow.
We start with a pilot project to align on the scope, schema, and acceptance criteria before scaling production. From there, our trained in-house annotation team follows project-specific guidelines in a workflow tailored to your use case, while reviewers and automated checks validate segments, transcripts, and attributes against agreed metrics.
Any discrepancies are caught early through staged deliveries and QA summaries, which helps keep annotation quality consistent from the first batch through final handoff.
We don’t have a strict minimum in terms of data volume. Instead, we approach each project based on its complexity, annotation type, and quality requirements.
For example, labeling 100 images with one object per frame using bounding boxes might take just a few hours. But 100 images with 10+ objects per frame, labeled with polygons or instance masks, would be significantly more time-consuming and costly. Because of this variability, we scope projects individually and provide a tailored quote after reviewing your dataset and requirements.
That said, our minimum project budget starts at $5,000. This helps ensure we can allocate the right experts, maintain quality control, and deliver results that meet our standards. If you're unsure whether your project fits, feel free to reach out — we're happy to review your data and advise.
Choose CVAT when you need both annotation capacity and technical depth. We combine 300+ annotators across 12 time zones, 10+ years of experience building annotation software, an in-house platform tailored to your workflow, and a quality-first labeling culture backed by trained in-house specialists.
You also get a free pilot project to validate quality early, along with secure handling through NDAs, GDPR and CCPA principles, customer cloud storage integrations, and isolated role-based workspaces.
Our typical turnaround time for contracted projects is approximately 1 month, though we always strive to deliver results faster when possible.
Absolutely. We maintain a team of 300+ qualified annotators that we can scale up or down based on your volume requirements. We can also adjust our resources to match your data collection and training workflow and provide continuous annotation support through our subscription service model.
Your data will be handled by our in-house team of annotation specialists. Each team member has undergone comprehensive training and has experience with dozens of annotation projects, ensuring consistent, high-quality results.
Getting started is simple. Fill out our contact form to discuss your project requirements and timeline.
Yes, we encourage pilot projects. During the project evaluation stage, we offer a free proof of concept that allows us to assess your data and requirements, define the budget, demonstrate our annotation quality, and introduce you to the CVAT platform where we perform the labeling work.