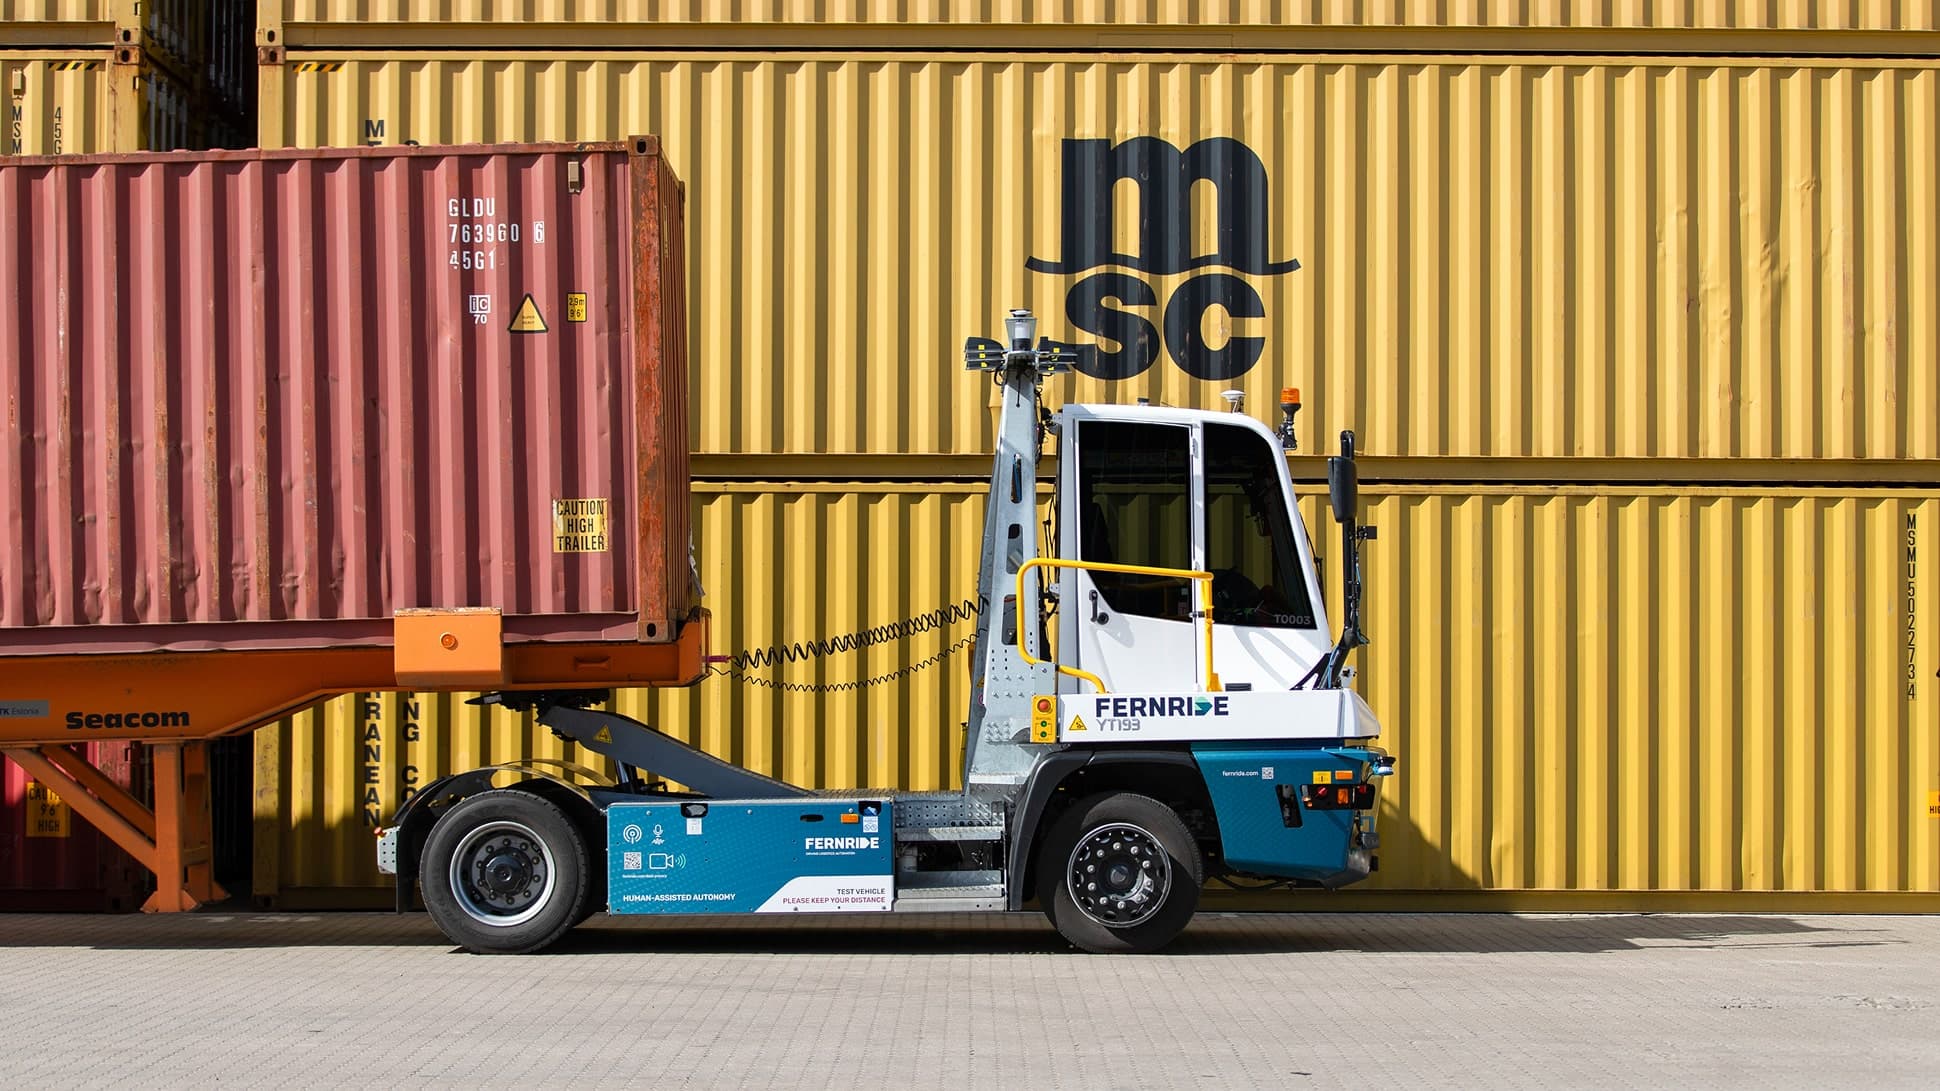
Sharper motion tracking and scene understanding for safer autonomous trucks.
Read the story- faster labeling workflows
- 30%
- annotation accuracy
- Higher
Beyond Vision: CVAT Goes Multimodal and Introduces Audio Annotation. Learn more

CVAT turns camera, LiDAR, and radar drives into validated training data for the corner cases behind perception failures, trusted in production by autonomy teams like FERNRIDE.
Use cases
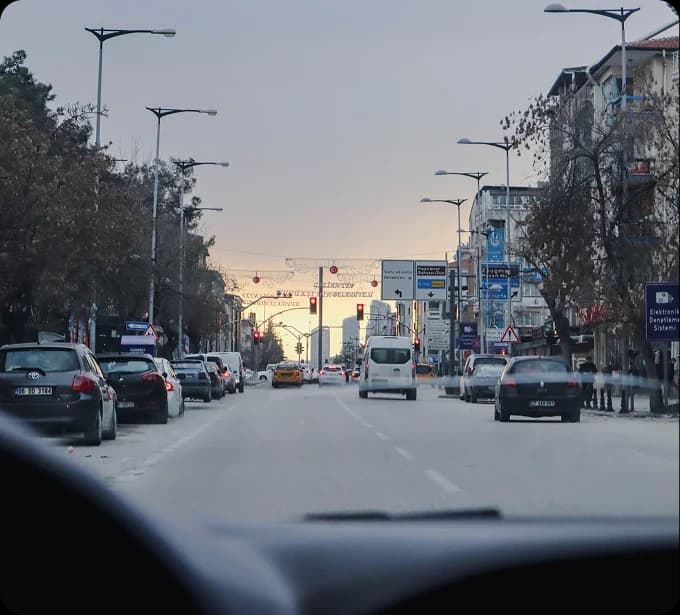
Track road agents in 2D camera frames and 3D LiDAR and radar point clouds.
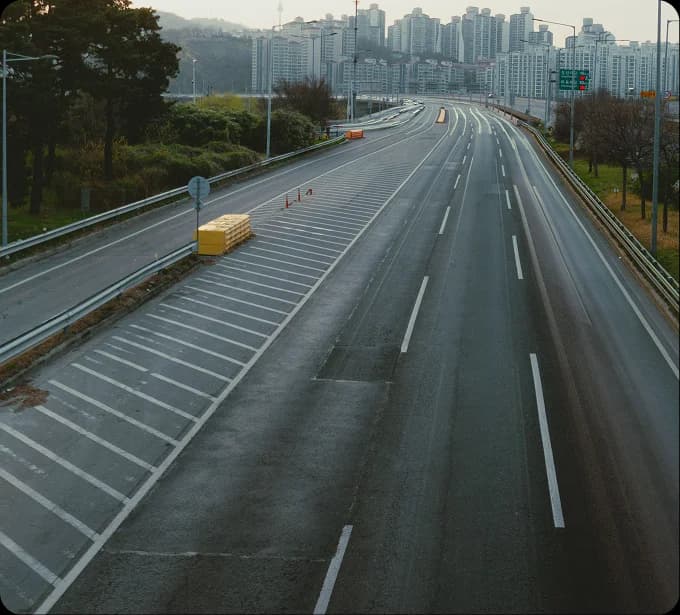
Isolate drivable free space, lane markers, and boundaries.
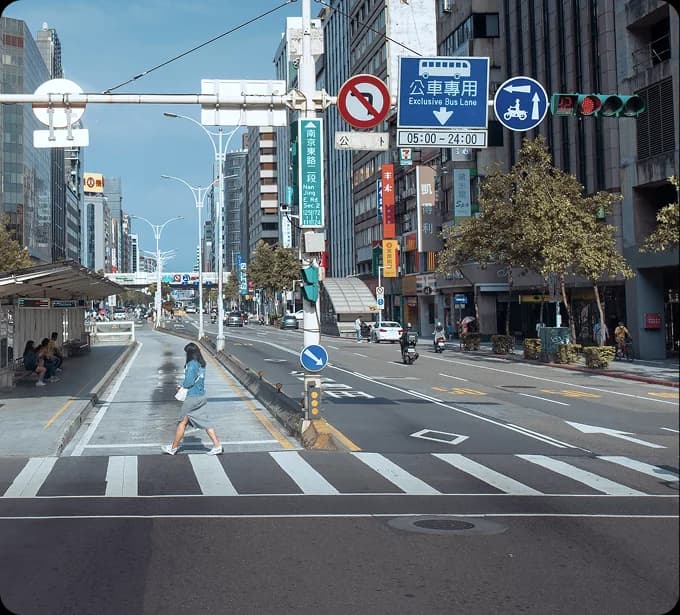
Detect and catalogue thousands of local traffic assets.
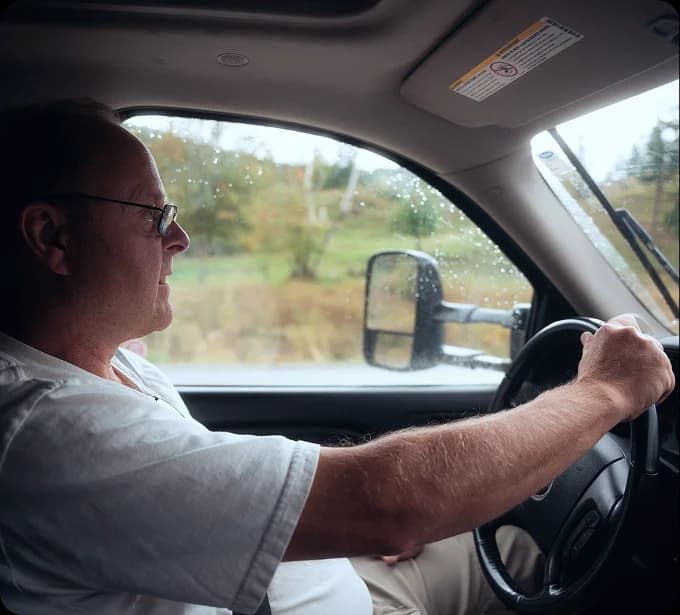
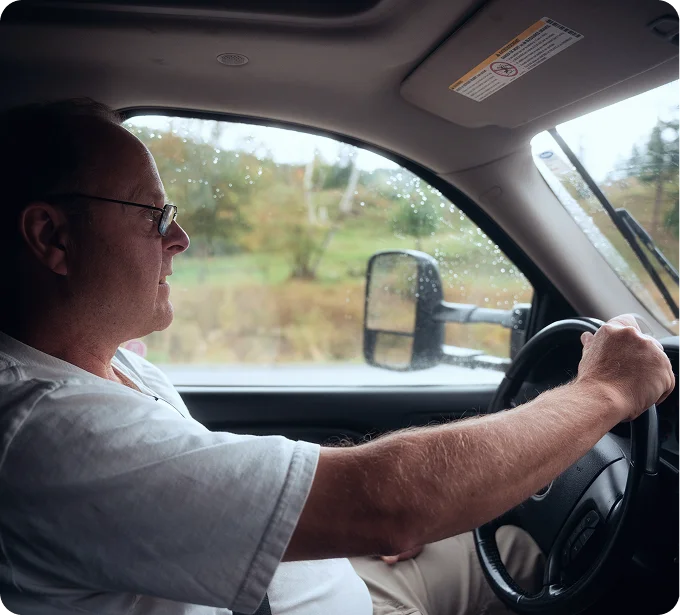
Track eye gaze, head pose, and drowsiness signals.
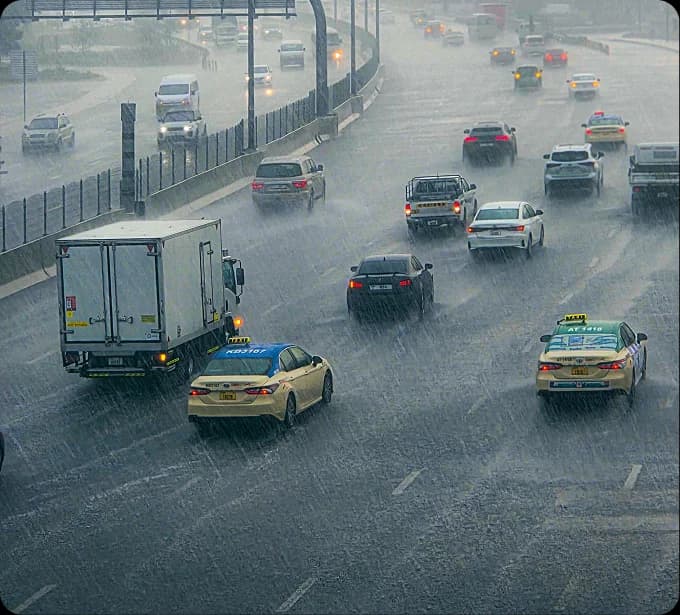
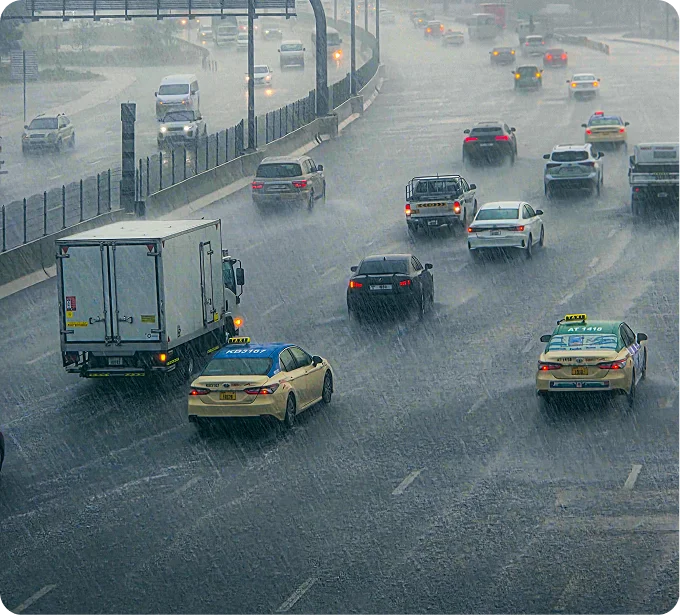
Annotate rare scenarios, adverse weather, and near-miss events.
Integrate Seamlessly
Connect your storage, labels, and review stages as they are. Nothing to re-plumb.
Book a demoAccelerate Validation
AI pre-labels every frame. Your team or our experts fix what it misses.
Book a demo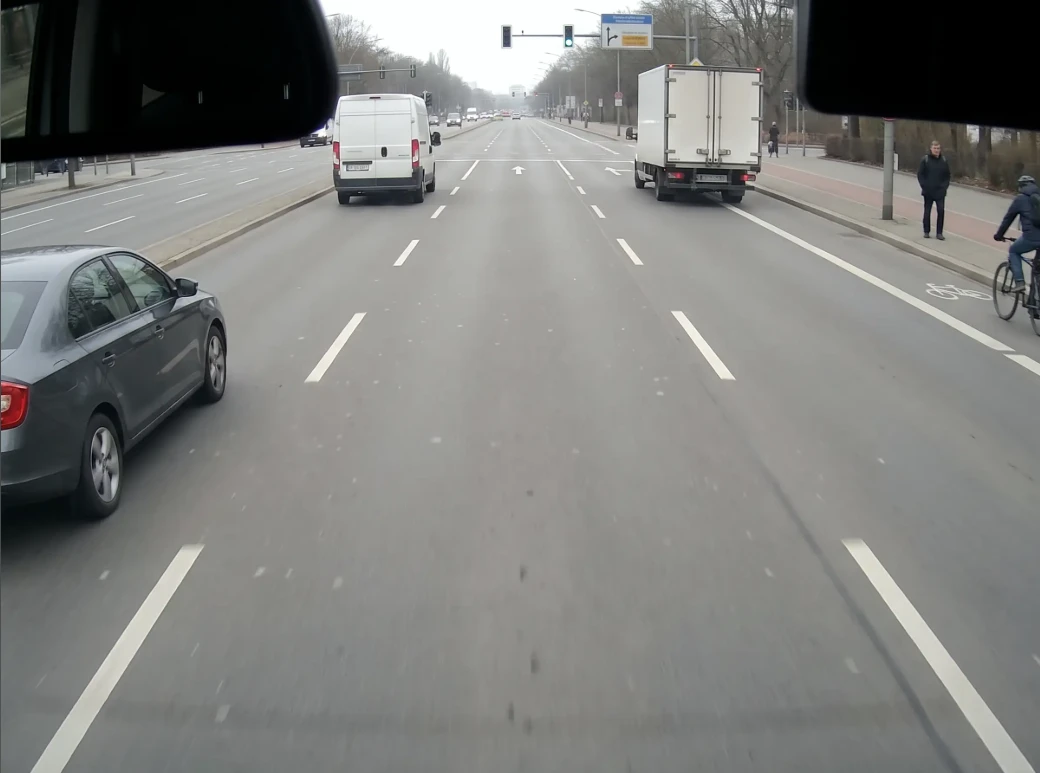
Ship with Confidence
Every job is scored against ground truth, so only clean data reaches training.
Book a demoMean annotation quality
98.4%
Target 95%
Honeypots
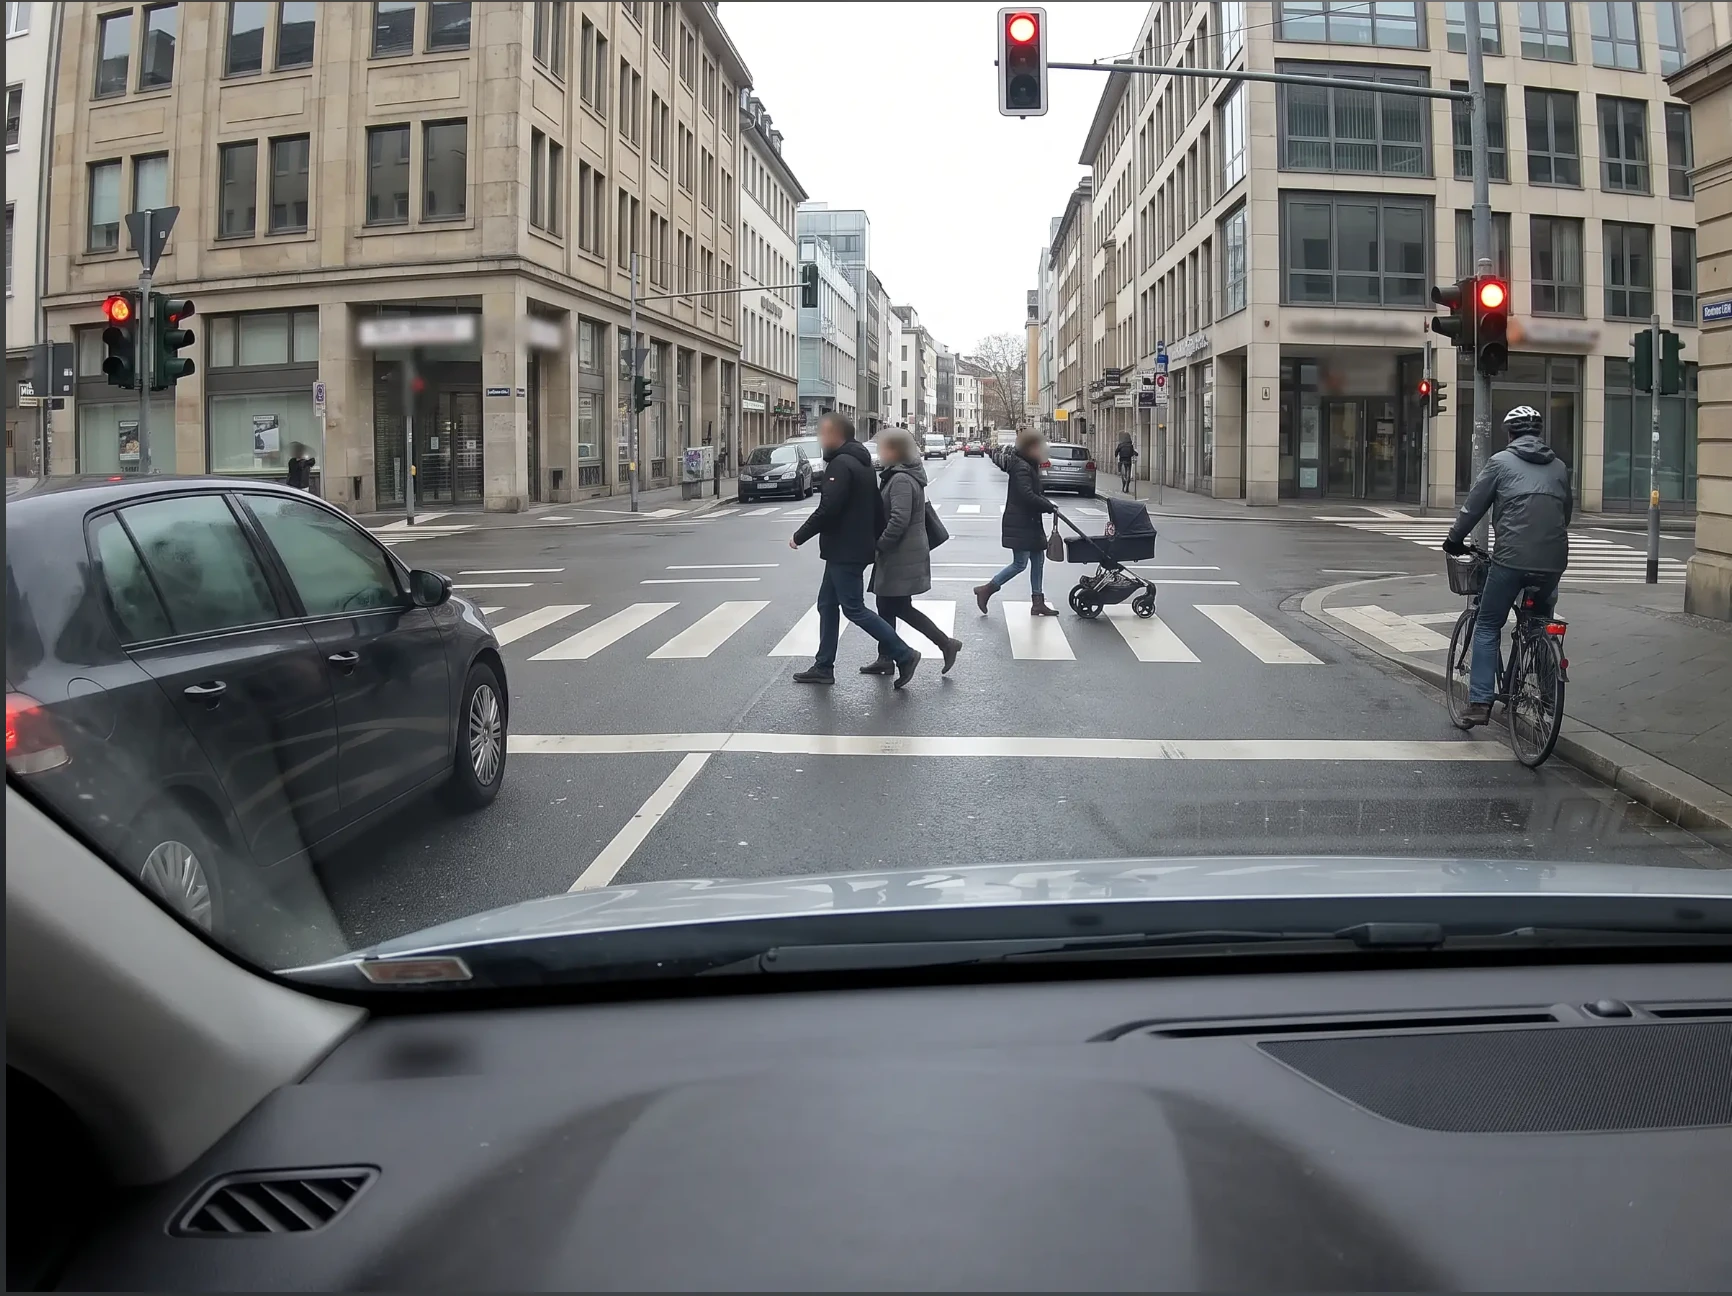
Sharper motion tracking and scene understanding for safer autonomous trucks.
Read the story